
LLM RAG accuracy evaluation
Evaluates retrieval accuracy and answer relevance, detects hallucination risks, and provides tuning guidance for continuous improvement.
EZIS for LLM RAG combines accuracy evaluation with operational monitoring to improve the reliability and performance of LLM RAG services.
Evaluates retrieval accuracy and answer relevance, detects hallucination risks, and provides tuning guidance for continuous improvement.
Monitors Vector DB metrics and document retrieval in real time and helps optimize hyperparameters for better matching and answer accuracy.
Tracks LangChain APIs, server CPU and memory, active users, request volume, average response time, and error rates in one view.
Evaluates answer relevance, semantic agreement with ground truth, answer similarity, retrieved-context relevance and coverage, context utilization, and groundedness.
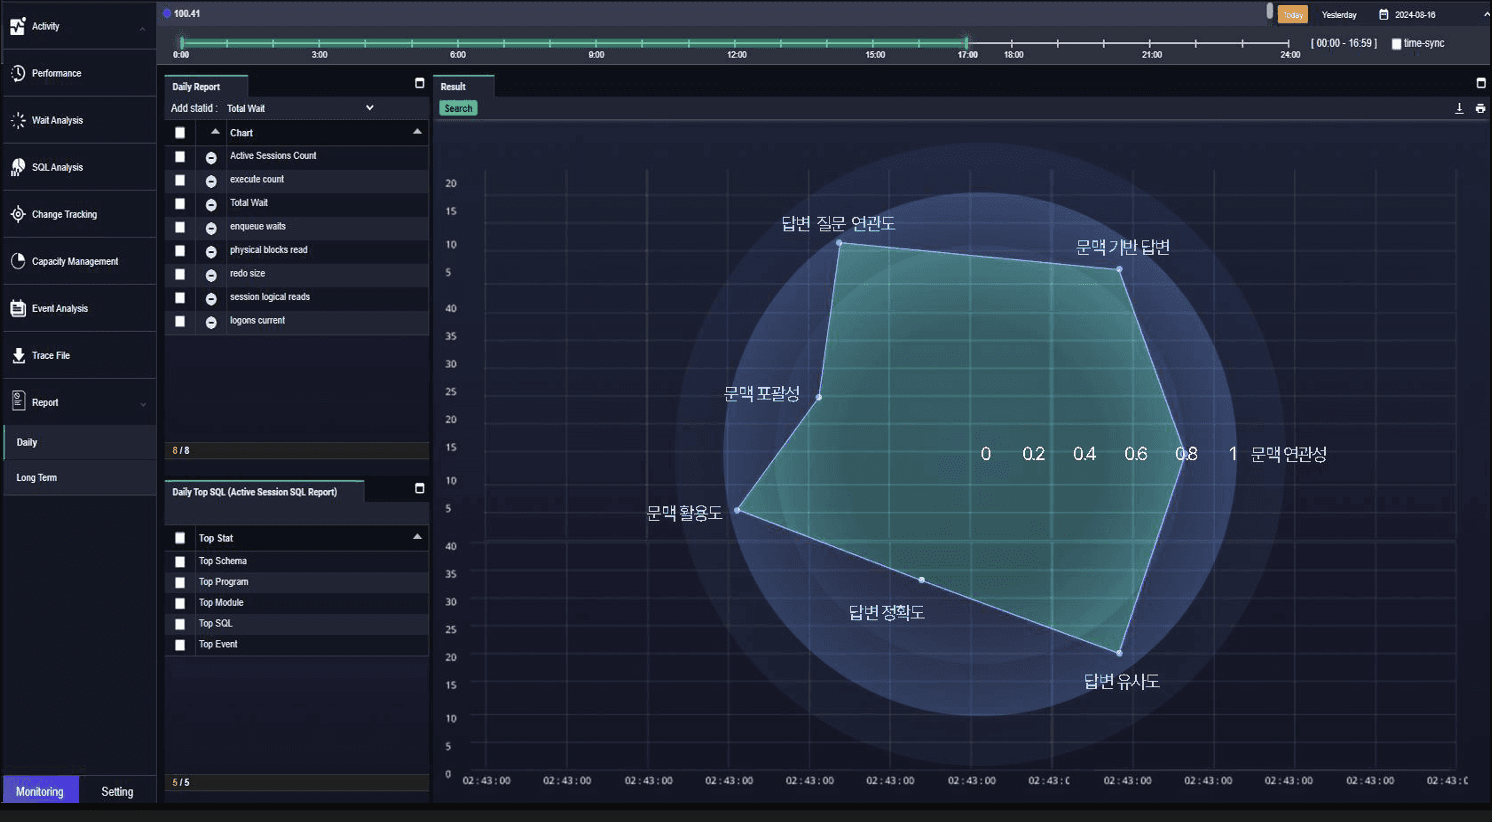
Automatically generates test questions to validate retrieval performance and compares vector similarity and distance across preprocessing, embedding, and indexing methods. The selected metrics become baselines for production analysis.
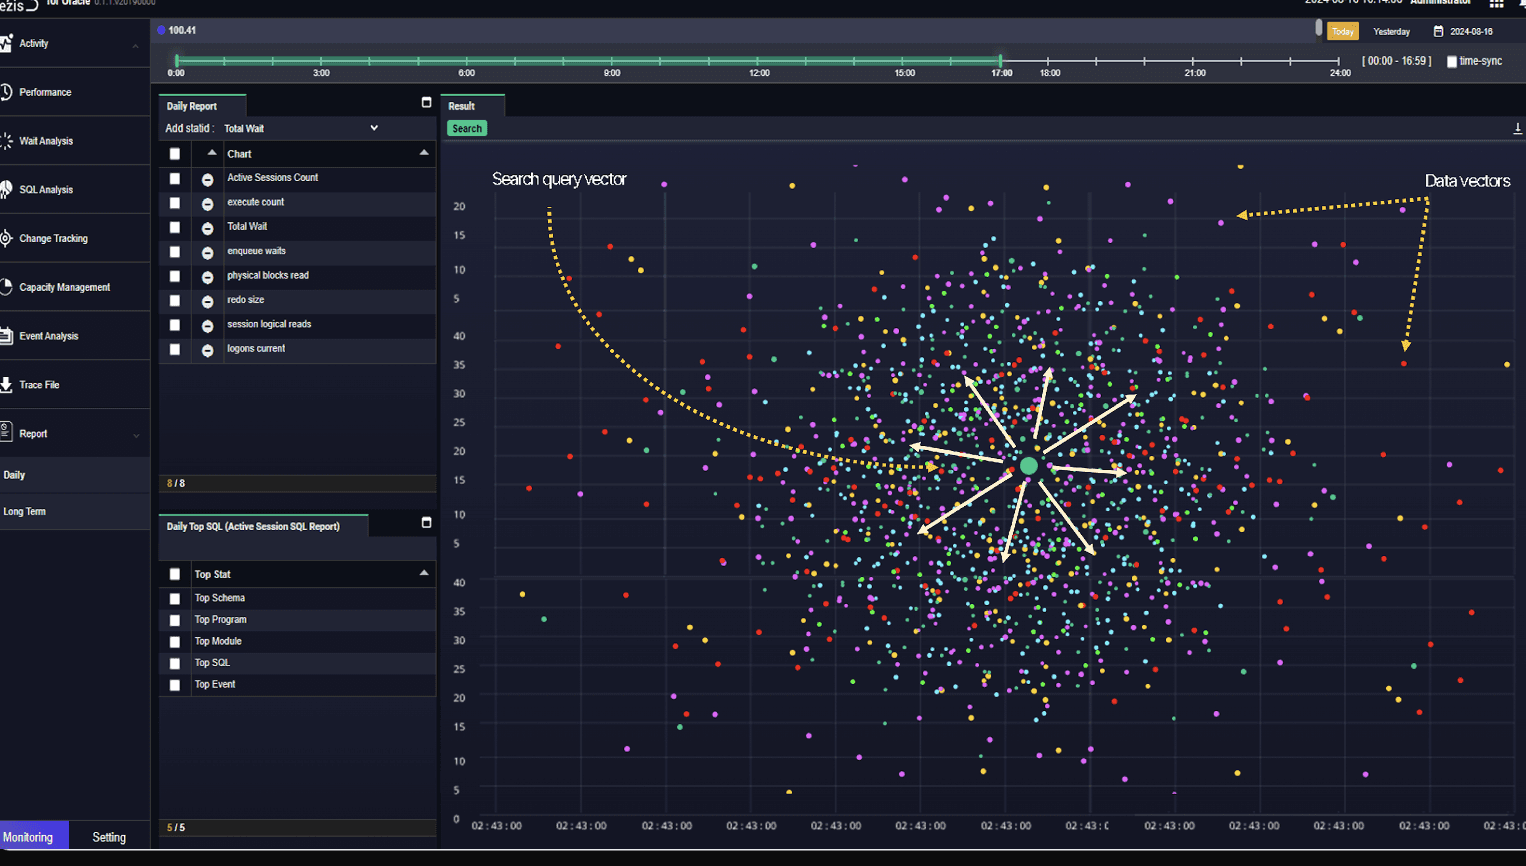
Visualizes average vector similarity and key server metrics, then uses alerts to identify answer-quality and retrieval-error risks. Query and retrieved-document IDs are logged for continuous quality management.